方建杰 Jianjie Fang

关于我About Me

我是清华大学深圳国际研究生院数据科学和信息技术专业2025级的硕士研究生,由陈鑫磊副教授、高宸助理研究员和李勇教授共同指导。研究关注具身智能与世界模型:如何让模型理解环境、预测动作带来的变化,推动物理智能发展。

I am a 2025 master's student in Data Science and Information Technology at Tsinghua Shenzhen International Graduate School, co-advised by Xinlei Chen, Chen Gao, and Yong Li. I work on embodied intelligence and world models: how a model understands its environment, predicts the consequences of actions, and advances physical intelligence.

目前在 Manifold AI(流形空间)主导世界模型训练,由高宸、武伟和李勇指导。课余我徒步、摄影、登山、攀岩,也坚持长跑,是多个户外协会领队,并且入选凯乐石-领攀签约摄影师。

I lead world-model training at Manifold AI, advised by Chen Gao, Wei Wu, and Yong Li. Outside research I hike, photograph, mountaineer, climb, and keep up distance running. I lead several outdoor clubs and am a KAILAS Lingpan signed photographer.

世界模型World Models 具身智能Embodied AI 空间智能Spatial Intelligence 多模态大模型Multimodal Large Models

教育经历Education

  • 2025.09 – 至今Present

    清华大学Tsinghua University

    深圳国际研究生院,数据科学和信息技术,学术型硕士。院系内年级排名 1/1428。

    Shenzhen International Graduate School, M.S. in Data Science and Information Technology. Ranked 1/1428 in the cohort.

  • 2021.09 – 2025.07

    东北大学Northeastern University

    计算机科学与技术,工学学士。专业综合 1/199。2023/2024 国家奖学金,2025 东北大学文浩命名奖学金(仅 1 位),十佳本科生,十佳双创之星。

    B.Eng. in Computer Science and Technology. Comprehensive ranking 1/199. National Scholarship in 2023 and 2024, the 2025 Northeastern University Wenhao Named Scholarship (sole recipient), Top 10 Undergraduate, and Top 10 Innovation Star.

实习经历Internships

  • 2025.12 – 至今Present

    Manifold AI

    世界模型 Worldscape 总负责人。总负责世界模型训练,统筹数据飞轮,并规划训练。由高宸、武伟和李勇指导。

    Overall lead of the Worldscape world model. I am in overall charge of world-model training and the data flywheel, and plan the training. Advised by Chen Gao, Wei Wu, and Yong Li.

  • 2026.04 – 至今Present

    ByteDance Seed

    实习。主导内部 VLA 具身基座模型训练。

    Intern. I lead training of an internal VLA embodied foundation model.

近况News

代表性工作Selected Research

NeurIPS 2026 CCF-A

Worldscape-MoE: A Unified Mixture-of-Experts World Model for Scalable Heterogeneous Action Control

Fang J*, Xu Y*, Wang Z*, Gao C*, Huang Y, Wang Z, Tang R, Jia M, Zhao B, Zhang W, Zhang X, Su H, Shang Y, Wu W, Chen X, Li Y

面向异源动作控制的 MoE 世界模型:共享专家学习跨控制的世界动态,专属专家吸收不同控制接口,并支持向新控制方式扩展。

A mixture-of-experts world model for heterogeneous action control. Shared experts learn dynamics that transfer across controls, while control-specific experts absorb each interface and extend to new ones.

ICML 2026 CCF-A

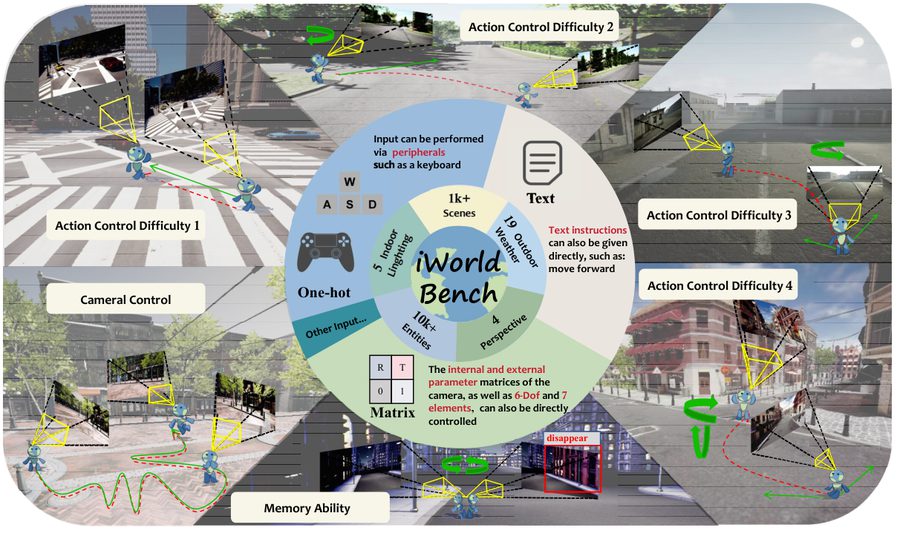
iWorld-Bench: A Benchmark for Interactive World Models with a Unified Action Generation Framework

Fang J, Lei Y, Wan Q, Wang Z, Huang Y, Xu Y, Zhao B, Zhang W, Gao C, Chen X, Li Y

用统一动作生成框架把异构动作接口放进同一评测协议,并提供数据、任务和公开榜单,使不同世界模型可以公平比较。

A unified action-generation framework that places heterogeneous control interfaces under one evaluation protocol, with data, tasks, and a public leaderboard.

arXiv 2026

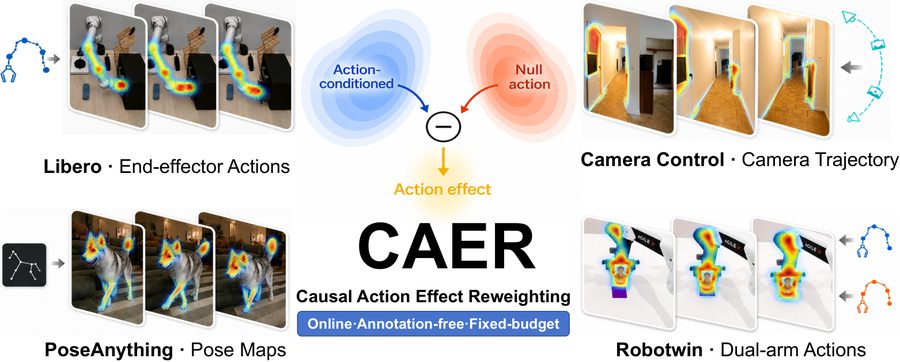
CAER: Causal Action Effect Reweighting for World Model Training

Fang J*, Liu X*, Wang Z, Tang R, Wang Z, Li Z, Zhang X, Su H, Gao C, Wu W, Chen X, Li Y

按动作真正改变的区域重新分配训练监督,让世界模型学习动作如何改变场景,而不是被大量背景像素主导。

Reweights training toward the regions an action actually changes, so a world model learns action effects instead of fitting abundant background pixels.

arXiv 2026

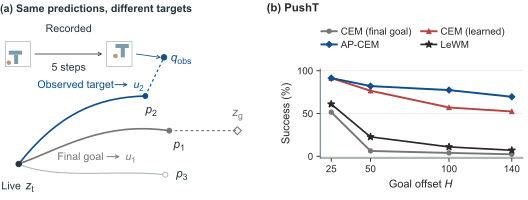
Aim Short to Reach Far: Your Frozen World Model Can Plan Better Than You Think

Liu X*, Fang J*, Wu W, Gao C, Li Y

不额外训练规划头,只把冻结世界模型的短期目标锚到自身轨迹上的近处观测,从而把长程规划做远。

A training-free method that aims a frozen world model at a nearby observation along its own trajectory, so short-horizon search can reach long-range goals.

arXiv 2026

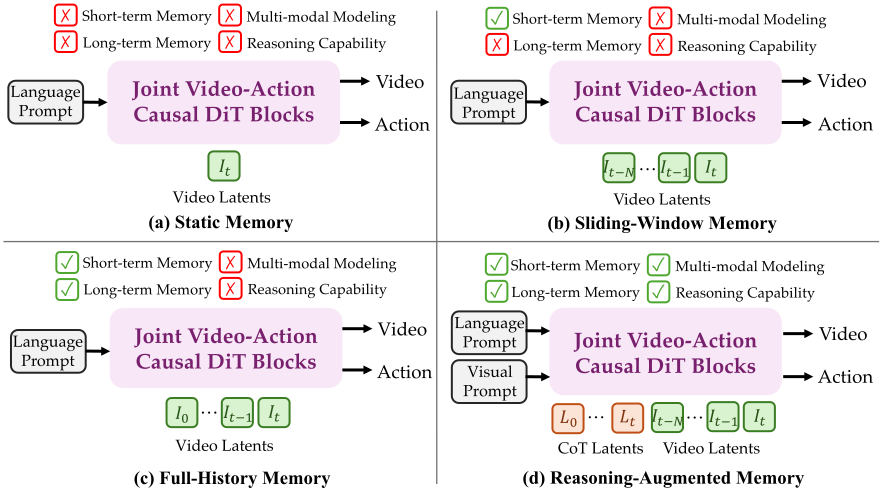
WorldScape Policy 2.0: Empowering Steerable World Action Modeling with Reasoning-Augmented Memory and In-Context Learning

Su H, Liu Z, Jin X, Dou H, Hu C, Li B, Liu Z, Xu R, Fang J, Zhang X, Yang Z, Yang X, Gao C, Yan J, Li Y, Wu W

用推理增强的长短时记忆和上下文学习,让世界动作模型既能按高层指令自主规划,也能按文本、目标图或视频细粒度执行。

A steerable world action model with reasoning-augmented memory and in-context learning, for planning from high-level instructions and control from text, goal images, or video.

论文Publications

arXiv 2026

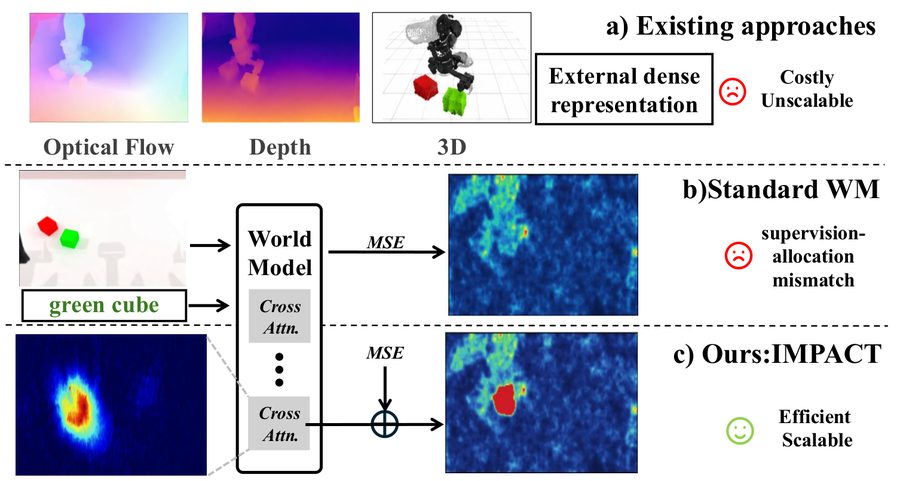
IMPACT: Attention Is the Interaction Map for Scalable Interaction-Aware World Model Training

Tang R*, Fang J*, Wang Z, Wang Z, Liu X, Su H, Zhang X, Wu W, Gao C, Li Y, Chen Z

用模型内部对操作物体的注意力作为交互图,把去噪监督集中到真正发生交互的区域,而不依赖外部标注。

Uses the model's own attention on manipulated objects as an interaction map, concentrating denoising supervision on interaction regions without external annotations.

arXiv 2026

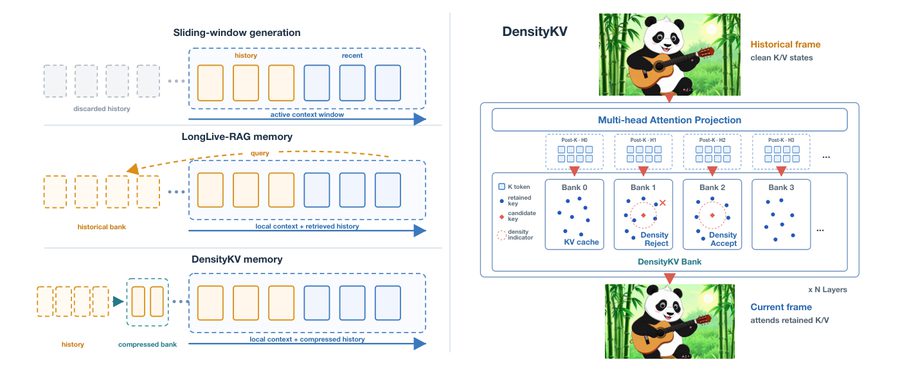
DensityKV: Density-Guided KV Cache Compression for Long Video Generation

Zhao W, Chi X, Zhang X, Ma G, Li B, Fang J, Tang P, Gao C, Wu W

按注意力键的局部密度压缩历史 KV 缓存,在存储不随生成长度增长的前提下保持长视频的主体和场景一致。

Compresses the historical KV cache by local key density, keeping long-video subjects and scenes consistent without storage that grows with generation length.

NeurIPS 2026CCF-A

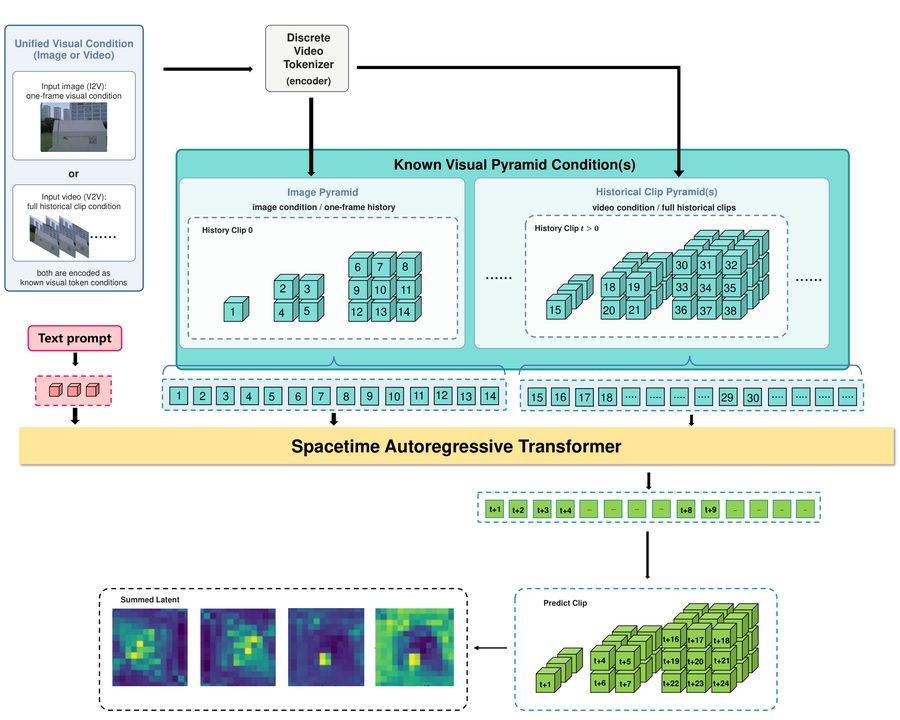
WorldVLN: Autoregressive World Action Model for Aerial Vision-Language Navigation

Zhao B, Xu J, Feng W, Zhang X, Wang Z, Wang H, Ji S, Wang Z, Fang J, Zheng Z, Zhang W, Shang Y, Wu W, Gao C, Chen X, Li Y

把空中视觉语言导航做成短时程世界状态预测,并把预测直接解码成可执行航点,形成闭环的世界动作模型。

Casts aerial vision-language navigation as short-horizon world-state prediction and decodes those predictions into executable waypoints in closed loop.

KDD 2026 · OralCCF-A

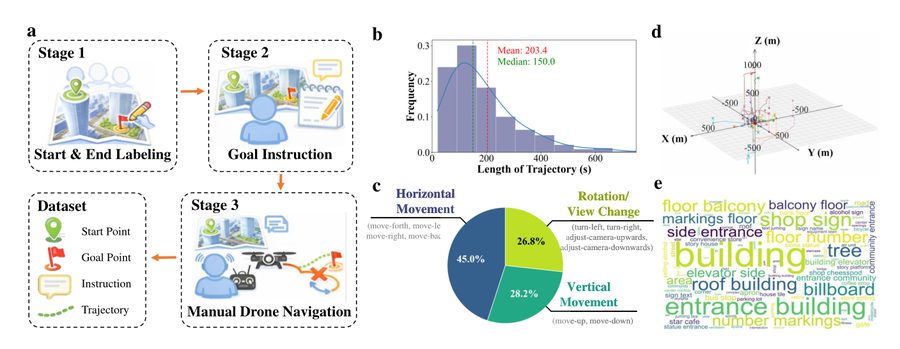
How Far Are Large Multimodal Models from Human-Level Spatial Action? A Benchmark for Goal-Oriented Embodied Navigation in Urban Airspace

Zhao B*, Wang Z*, Fang J*, Zhou Z, Xu Y, Ji Y, Xu J, Zhang Q, Zhang W, Gao C, Chen X

用 5037 条城市空域目标导航样本评测 17 个模型,衡量大模型离人类水平的空间行动还有多远。

A goal-oriented navigation benchmark in urban airspace, with 5,037 samples and an evaluation of 17 models against human-level spatial action.

ACL 2025CCF-A

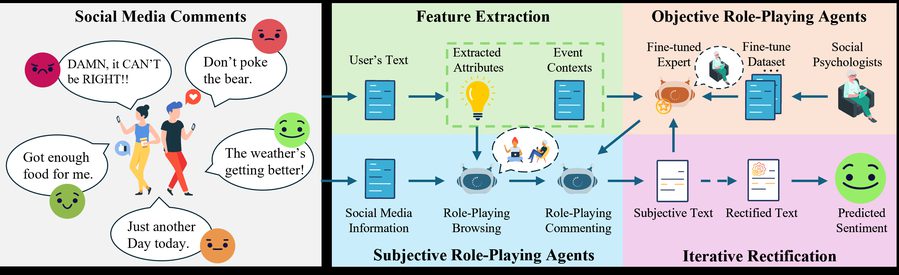
Context-Aware Sentiment Forecasting via LLM-Based Multi-Perspective Role-Playing Agents

Man F, Wang H, Fang J, Deng Z, Zhao B, Chen X, Li Y

用多视角角色扮演的大模型模拟人对事件的反应,预测社交媒体用户接下来的情绪,而不只是回顾已有发言。

Forecasts how social-media users will feel about unfolding events by role-playing multiple perspectives with large language models.

ICLR 2025 Workshop · Best Paper

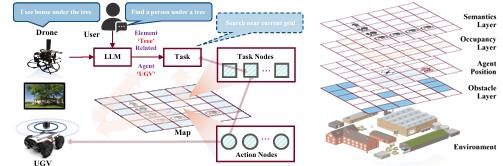
A Large Language Model-Driven Heterogeneous Air-Ground Search Swarm

Jian Z, Pu X, Fang J, Deng Z, Wang X, Chen X

用大模型为异构空地搜索群做集中任务分配,并把推理与执行异步解开,已在仿真和真实空地平台上完成搜救部署。

An LLM task-allocation framework for a heterogeneous air-ground search swarm, with asynchronous reasoning and execution, deployed in simulation and on a physical platform.

ACM MM 2025 · OralCCF-A

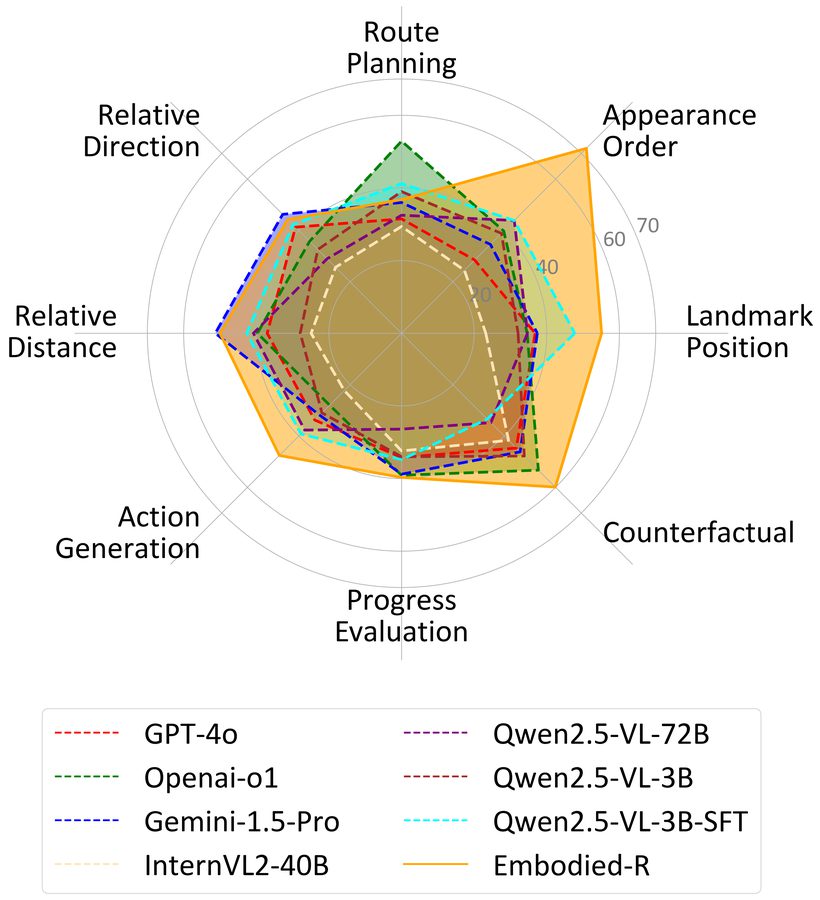
Embodied-R: Collaborative Framework for Activating Embodied Spatial Reasoning in Foundation Models via Reinforcement Learning

Zhao B*, Wang Z*, Fang J*, Gao C, Man F, Cui J, Wang X, Chen X, Li Y, Zhu W

大视觉语言模型负责感知、小语言模型负责推理,并用逻辑一致性奖励做强化学习;5k 条样本、3B 参数即可达到 o1 与 Gemini-2.5-Pro 的同等水平。

A large vision-language model perceives and a smaller language model reasons, trained with a logical-consistency reward. With 5k samples and 3B parameters it matches OpenAI-o1 and Gemini-2.5-Pro.

arXiv 2025

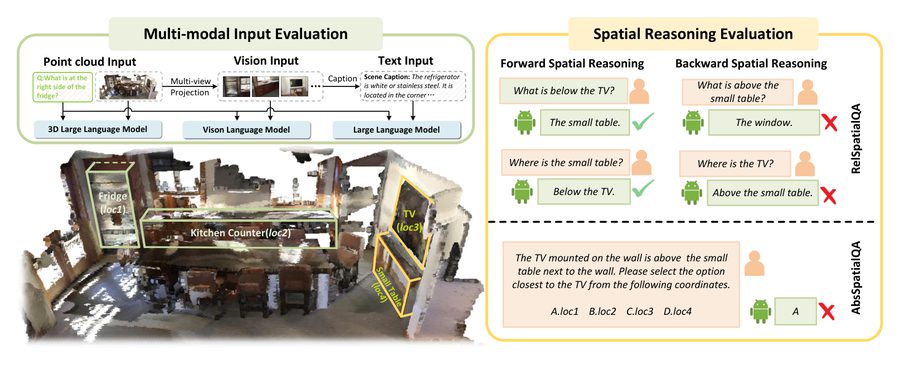
The Point, the Vision and the Text: Does Point Cloud Boost Spatial Reasoning of Large Language Models? A Bias-Controlled Study

Zhang W, Peng R, Zeng X, Fang J, Wang Z, Li K, Dong H, Li W, Gao C, Wang X, Chen X, Li Y

在同一套文本、图像和点云问答上比较三种模态,检验点云是否真能提升大模型的空间推理。

A bias-controlled study over text, vision, and point clouds that tests whether point clouds actually improve spatial reasoning in large language models.

ACM MM 2025CCF-A

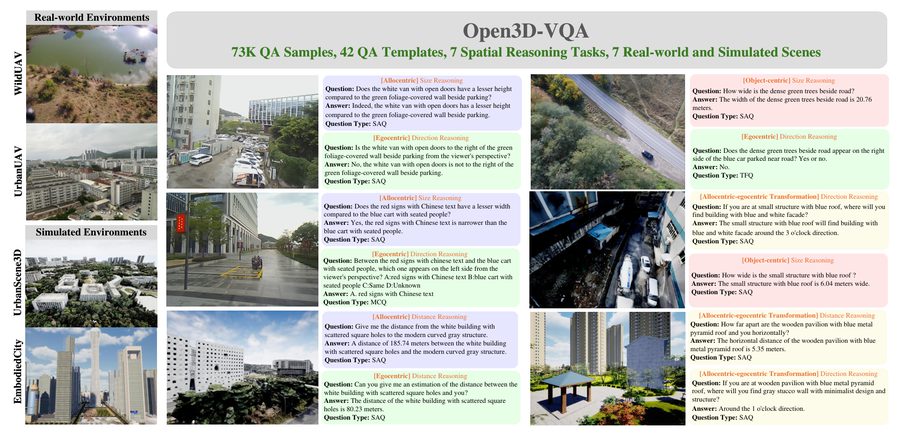
Open3D-VQA: A Benchmark for Embodied Spatial Concept Reasoning with Multimodal Large Language Model in Open Space

Zhang W*, Zhou Z*, Zeng X*, Liu X, Fang J, Gao C, Li Y, Cui J, Chen X, Zhang X

从航拍视角评测多模态大模型的开放空间关系推理,题目来自真实与仿真城市场景,同时支持图像和点云。

An aerial-view benchmark for spatial-relation reasoning, with questions from real and simulated city scenes and support for both images and point clouds.

ACL 2025 · OralCCF-A

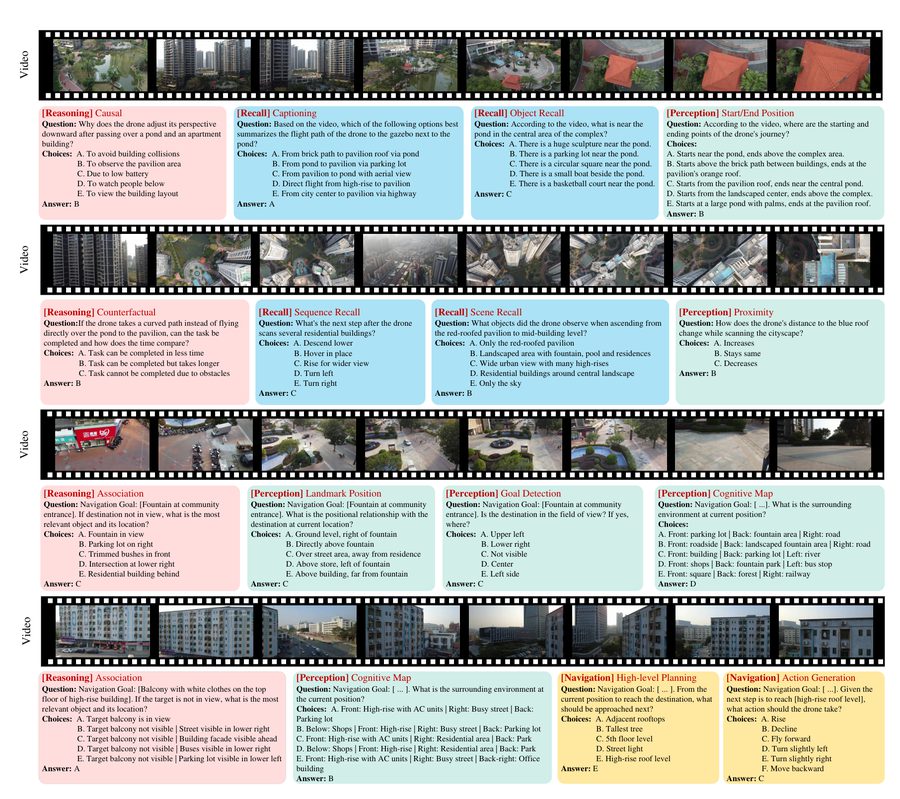
UrbanVideo-Bench: Benchmarking Vision-Language Models on Embodied Intelligence with Video Data in Urban Spaces

Zhao B*, Fang J*, Dai Z*, Wang Z, Zha J, Zhang W, Gao C, Wang Y, Cui J, Chen X, Li Y

用真实城市与仿真环境中的第一人称无人机视频,评测视频大模型在回忆、感知、推理和导航上的具身能力。

Evaluates whether video language models can recall, perceive, reason, and navigate from first-person drone video in real and simulated cities.

arXiv 2024

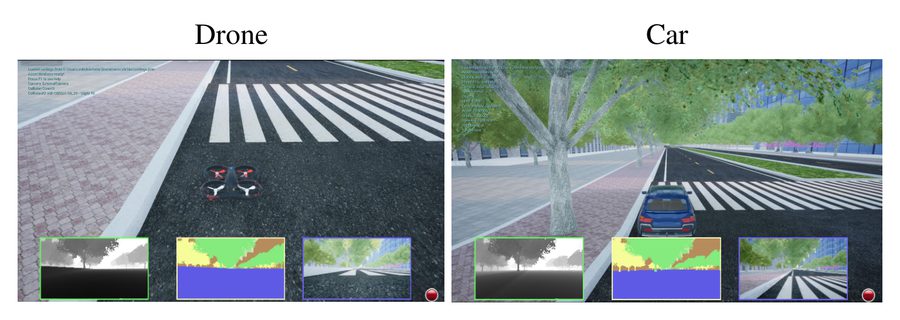
EmbodiedCity: A Benchmark Platform for Embodied Agent in Real-World City Environment

Gao C, Zhao B, Zhang W, Mao J, Zhang J, Zheng Z, Man F, Fang J, Zhou Z, Cui J, Chen X, Li Y

基于真实城市搭建的室外具身智能仿真平台,提供行人与车流,以及感知、规划、行动等评测任务和统一接口。

A city-scale embodied platform built from a real urban environment, with pedestrian and traffic flow, evaluation tasks, and a unified agent interface.

荣誉Honors

  • 清华大学三好学生,2025–2026 学年度Tsinghua University Merit Student, 2025–2026
  • 凯乐石领攀签约摄影师,2025.10KAILAS Lingpan signed photographer, Oct 2025
  • ICLR 2025 Workshop 最佳论文奖ICLR 2025 Workshop Best Paper Award
  • 2023/2024 国家奖学金National Scholarship, 2023 and 2024
  • 2025 东北大学文浩命名奖学金(仅 1 位)Northeastern University Wenhao Named Scholarship, 2025 (sole recipient)
  • 东北大学十佳本科生、十佳双创之星,2023Top 10 Undergraduate and Top 10 Innovation Star, Northeastern University, 2023

徒步与摄影Hiking and Photography